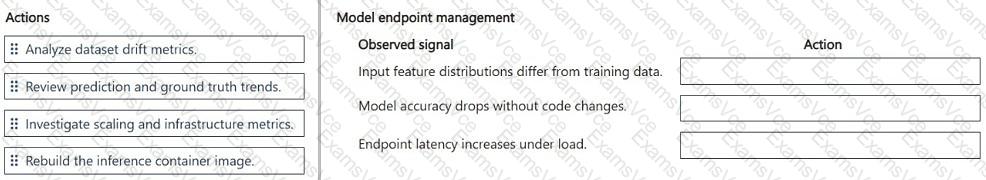
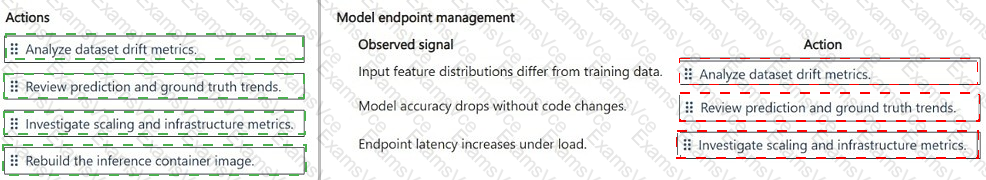
Input feature distributions differ from training data: Analyze dataset drift metrics
Model accuracy drops without code changes: Review prediction and ground truth trends
Endpoint latency increases under load: Investigate scaling and infrastructure metrics
When input feature distributions differ from training data , the correct action is to analyze dataset drift metrics . Azure Machine Learning model monitoring detects data drift by comparing the statistical distributions of production model inputs against reference data, commonly the original training dataset. Supported measures include Population Stability Index, Jensen-Shannon distance, normalized Wasserstein distance, and statistical tests such as Kolmogorov-Smirnov.
When model accuracy drops without code changes , the next investigation should focus on prediction and ground-truth trends . Azure Machine Learning model-performance monitoring compares production predictions with collected actual outcomes and can calculate classification metrics such as accuracy, precision, and recall. A declining score without deployment changes may indicate concept drift, prediction drift, or changing relationships between input features and target outcomes.
When endpoint latency increases under load , the issue is operational rather than primarily statistical. The team should investigate scaling and infrastructure metrics , including request latency, requests per minute, CPU/memory utilization, throttling, and replica capacity. Microsoft recommends using endpoint metrics to determine whether compute must scale up or out.
Rebuild the inference container image is not indicated by any of the observed signals.
Study Guide Reference: Implement machine learning model lifecycle and operations — production monitoring, data drift, model-performance monitoring, endpoint observability, and scaling.